I am Yu Xu (徐榆). I received my Ph.D. in Computer Science from University of Chinese Academy of Sciences in 2026, supervised by Prof. Juan Cao and Dr. Fan Tang.
Currently, I am a researcher on the Kling-Image Team at Kling AI, where I am responsible for foundation model pre-training. Prior to this, I was a Research Intern at ByteDance, working on unified multimodal video generation, and at Tencent Hunyuan, where my work focused on unified image generation models.
Before starting my Ph.D., I received my Master of Science in Computer Science from The University of Hong Kong, supervised by Prof. Benjamin Kao, where my research focused on Visual Question Answering. I also spent a wonderful time as a Research Assistant at Kyoto University in Japan, working on image enhancement algorithms supervised by Prof. Masaaki Iiyama and Dr. Atsushi Hashimoto.
My research interests lie primarily in generative AI, with a focus on large-scale pre-training of generative foundation models and unified multimodal modeling.
🔥 News
- 2026.09: 🎉🎉 Our paper SplitMoE has been accepted by NeurIPS 2026 as a Spotlight!
- 2026.08: 🎉🎉 Our paper Beyond Pixels has been accepted by SIGGRAPH ASIA 2026!
- 2026.02: 🎉🎉 Our paper TAG-MoE has been accepted by CVPR 2026!
- 2026.02: 🎉🎉 Our paper Re-align has been accepted by CVPR 2026!
- 2026.02: 🎉🎉 Our paper Meta-CoT has been accepted by CVPR 2026!
- 2026.02: 🎉🎉 Our paper GVCoT has been accepted by CVPR 2026-findings!
- 2026.01: 🎉🎉 Our paper HeadRouter has been accepted by ACM TOG 2026!
- 2025.08: 🎉🎉 Our paper In-Context Brush has been accepted by SIGGRAPH ASIA 2025!
- 2025.03: 🎉🎉 Our paper B4M has been accepted by ACM TOG 2025!
📝 Selected Publications
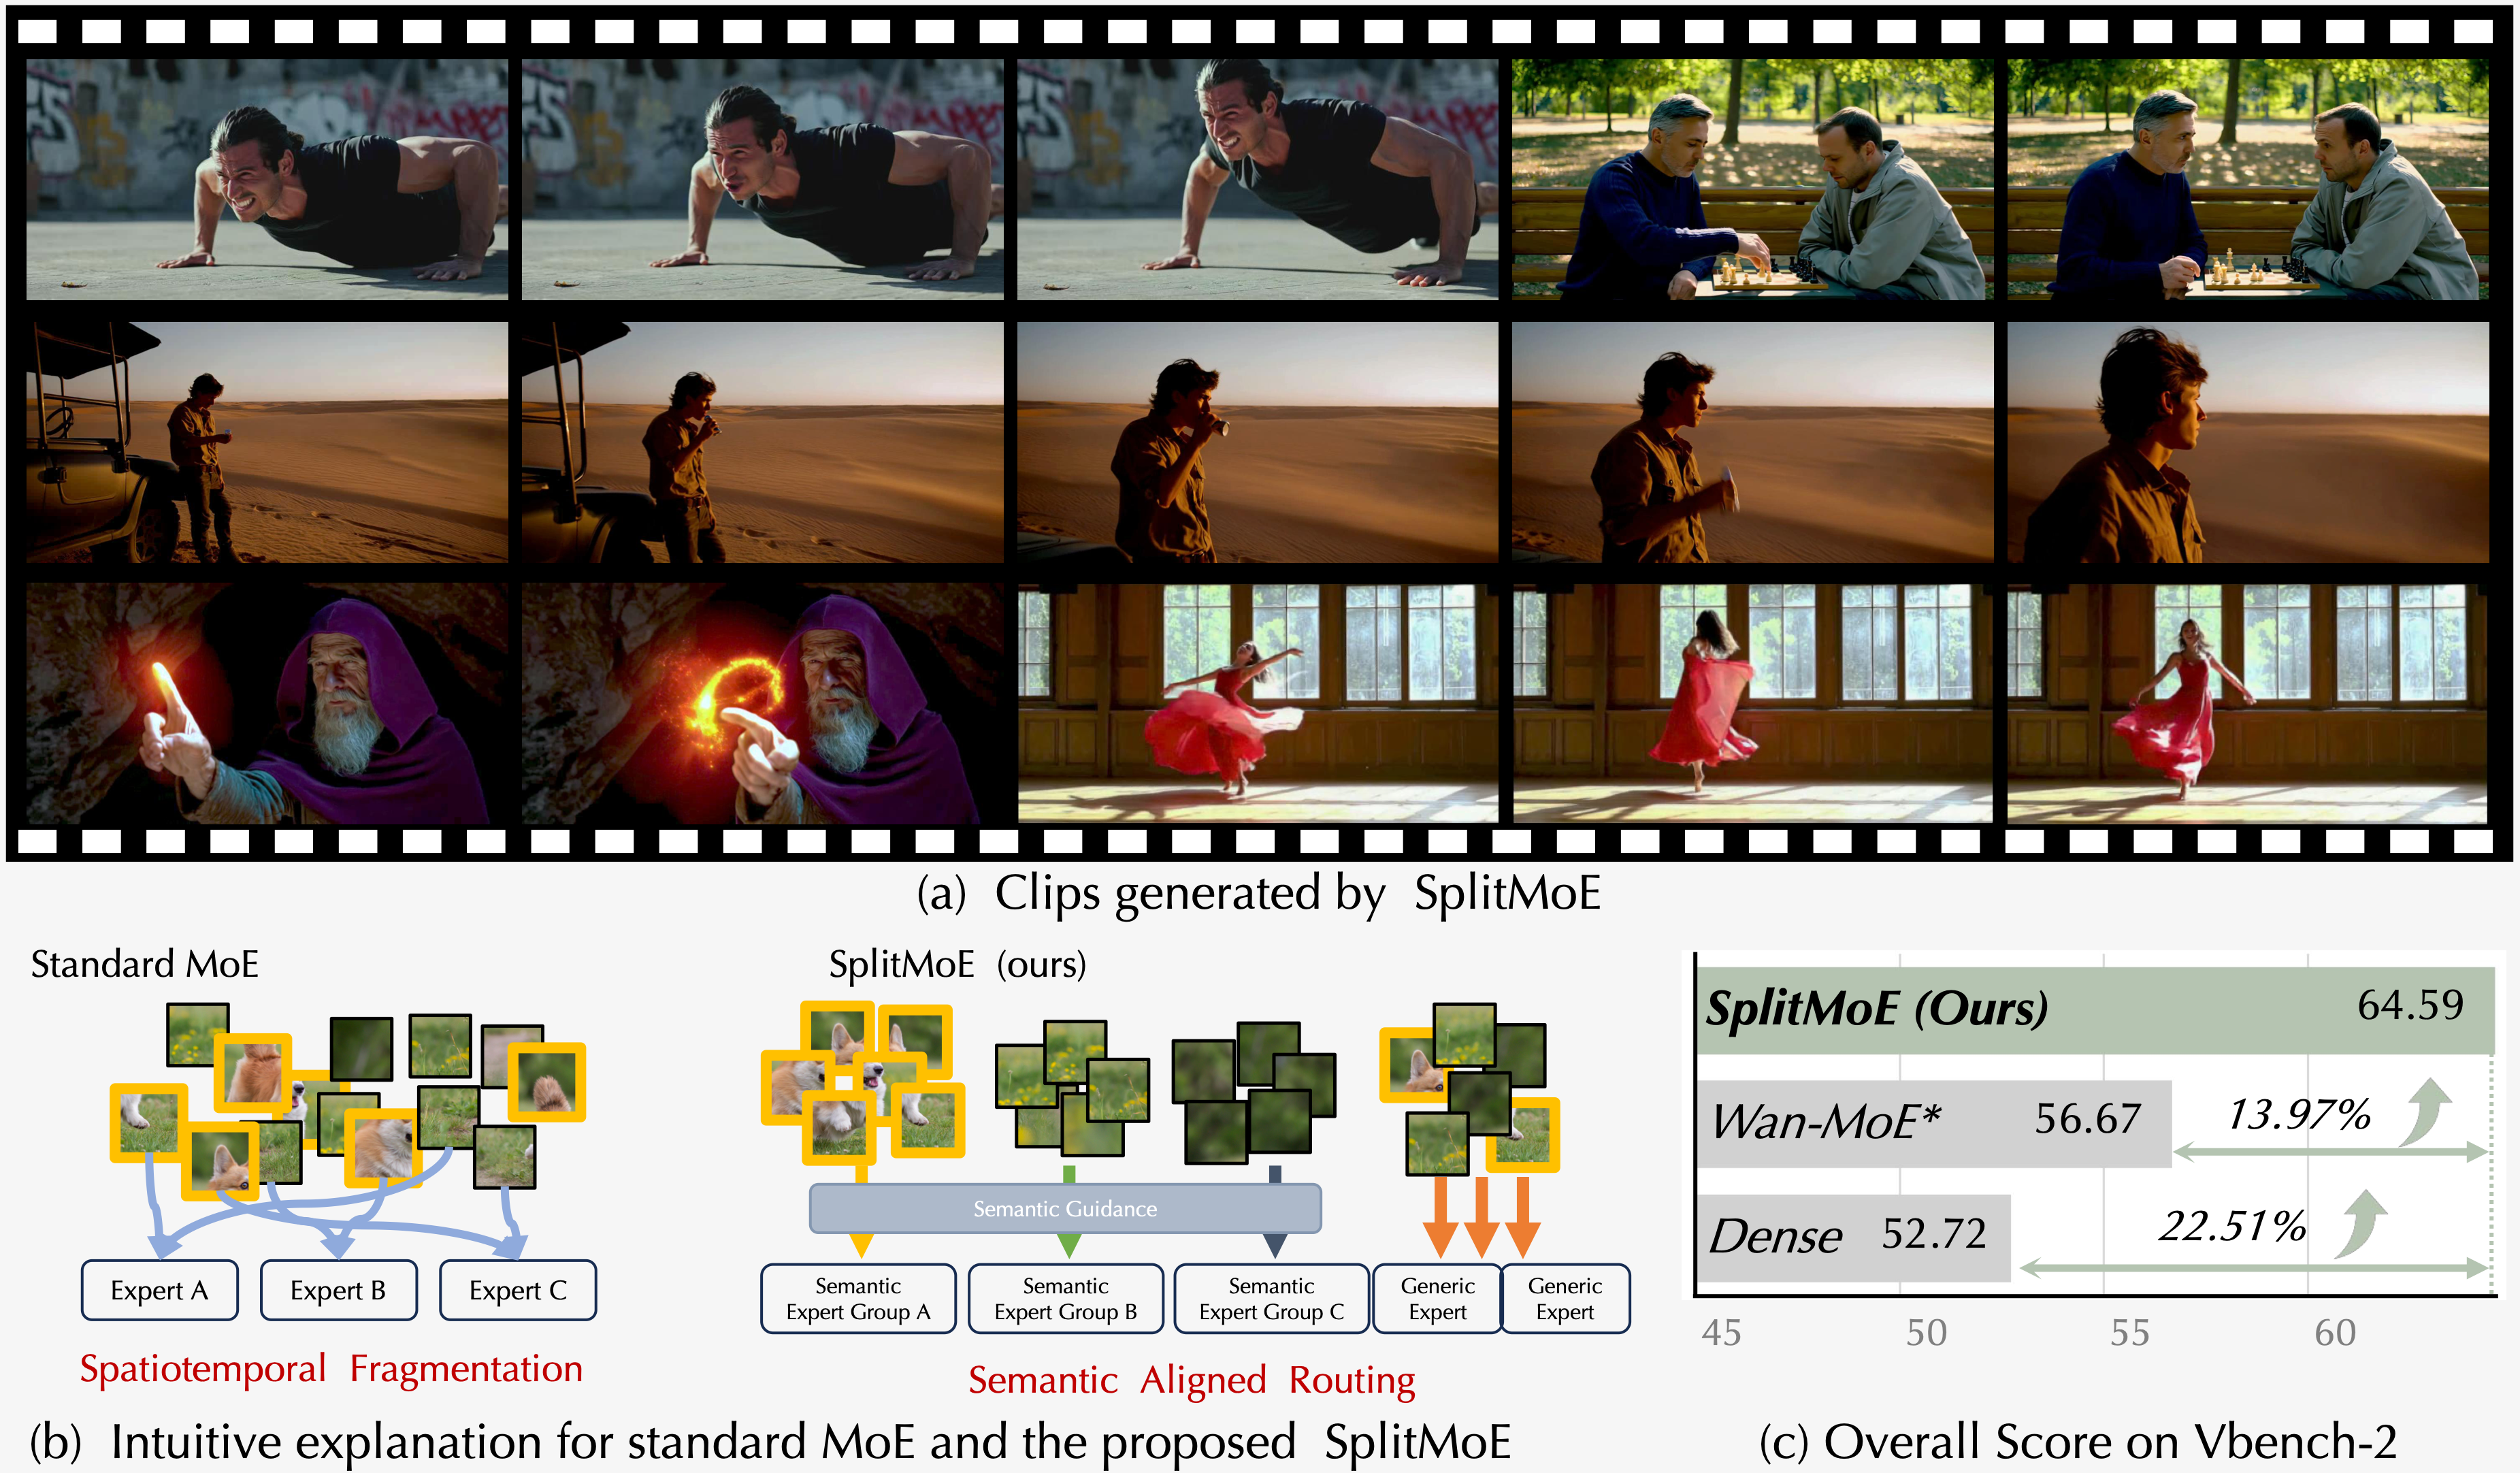
Breaking the Uniformity Trap: Scaling Video Diffusion Model via SplitMoE
Yu Xu, Yuxin Zhang, Xiao Yang, Haotian Yang, Yizhi Wang, Xinwei Huang, Minxuan Lin, Angtian Wang, Chongyang Ma, Fan Tang
TL;DR: SplitMoE escapes the “uniformity trap” of token-wise MoE in video diffusion by bifurcating the expert pool into semantic and generic experts with prototype-guided routing and pull-push regularization, achieving faster convergence, more coherent routing, and higher video quality under the same activated-parameter budget.
Conference on Neural Information Processing Systems (NeurIPS'26), Spotlight
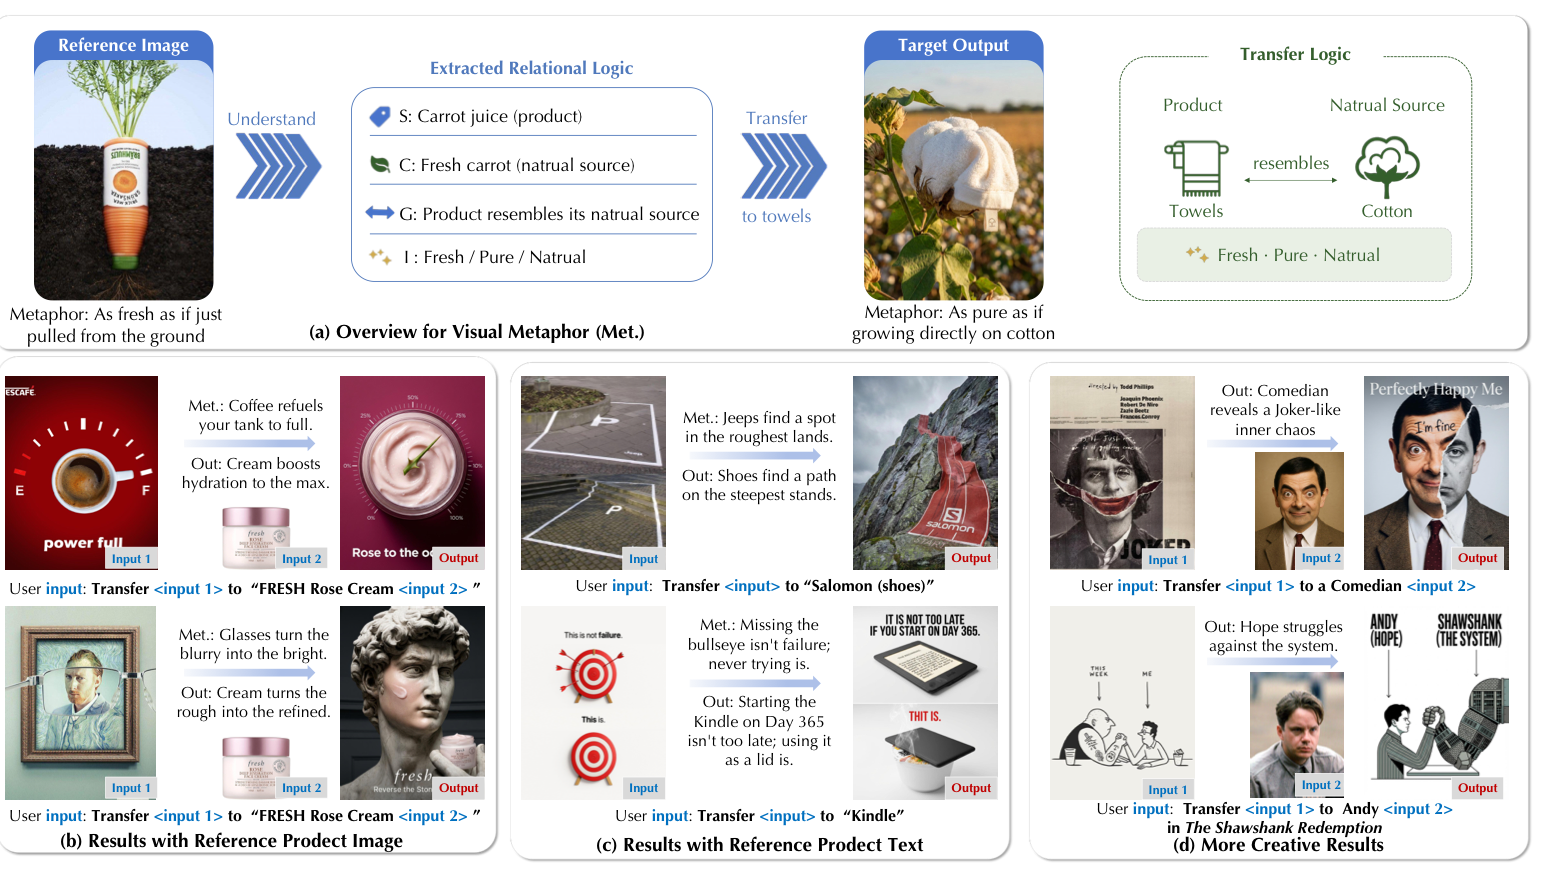
Beyond Pixels: Visual Metaphor Transfer via Schema-Driven Agentic Reasoning
Yu Xu, Yuxin Zhang, Lin Gao, Oliver Deussen, Tong-Yee Lee, Fan Tang
TL;DR: Beyond Pixels introduces the task of Visual Metaphor Transfer (VMT) and a cognitive-inspired multi-agent framework that distills the “creative essence” of a reference image into a structured Schema Grammar, then re-instantiates the abstract relational logic onto user-specified targets with closed-loop diagnostic backtracking.
ACM Special Interest Group on Computer Graphics and Interactive Techniques (SIGGRAPH ASIA'26)
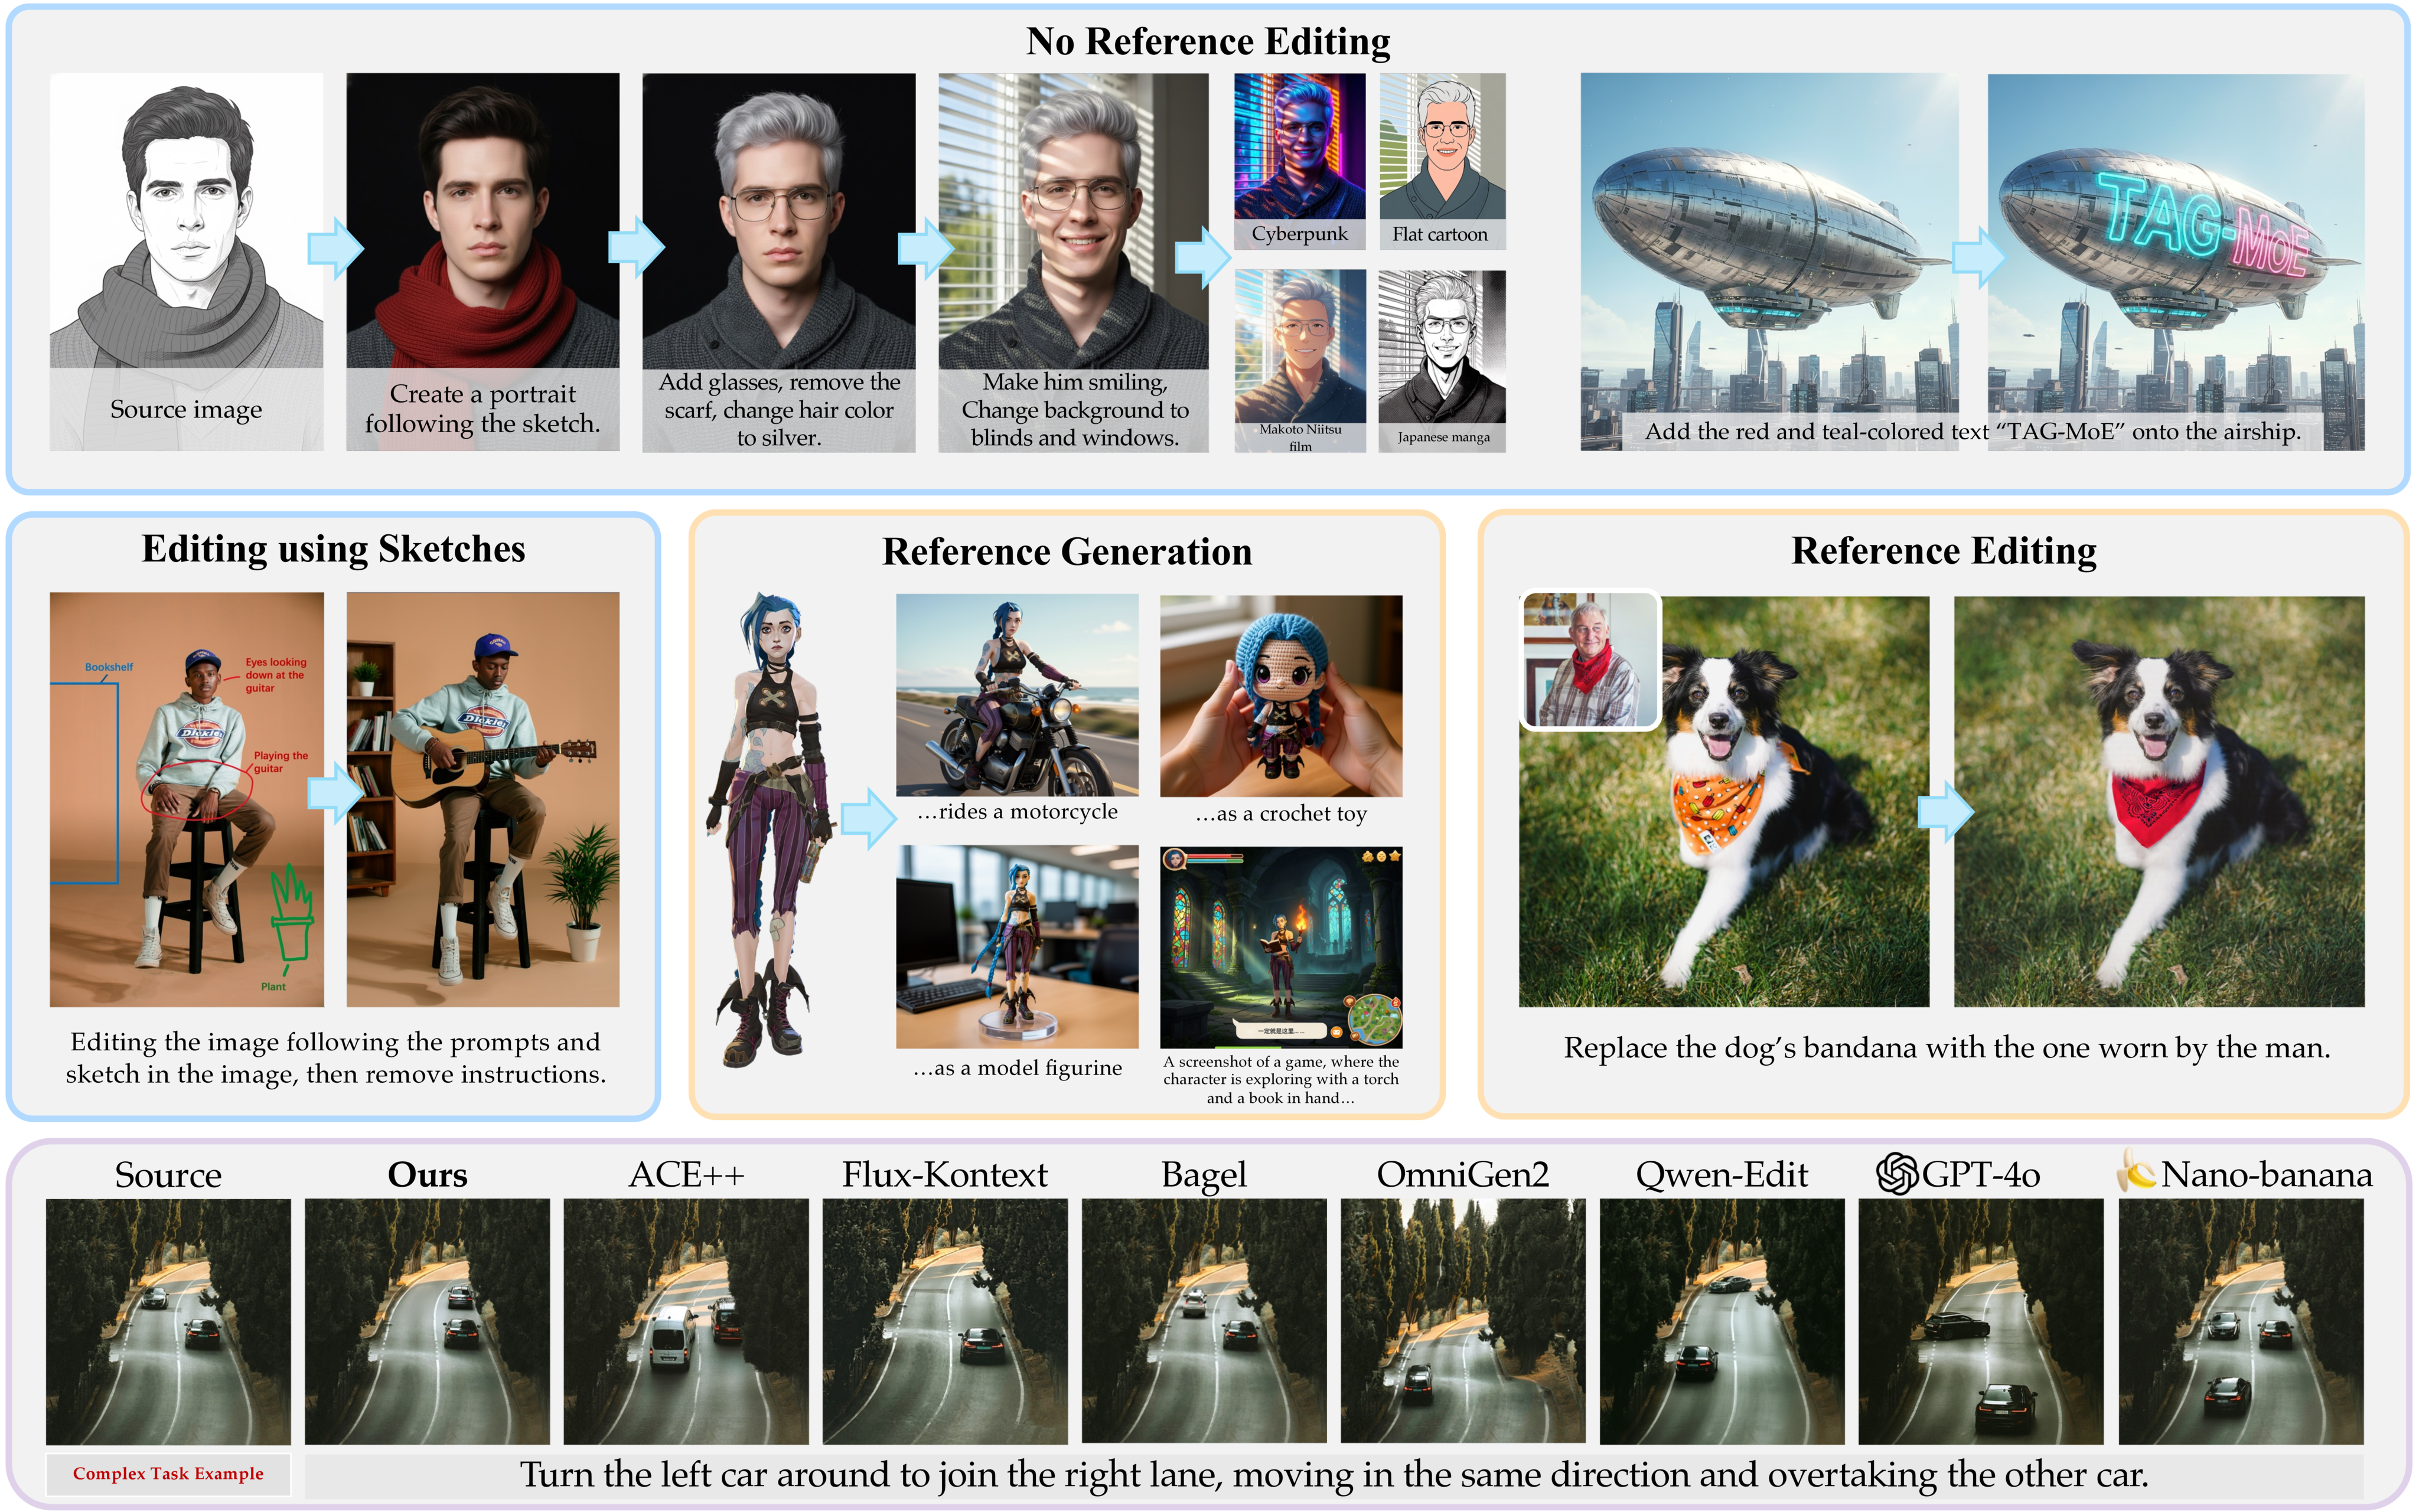
TAG-MoE: Task-Aware Gating for Unified Generative Mixture-of-Experts
Yu Xu, Hongbin Yan, Juan Cao, Yiji Cheng, Tiankai Hang, Runze He, Zijin Yin, Shiyi Zhang, Yuxin Zhang, Jintao Li, Chunyu Wang, Qinglin Lu, Tong-Yee Lee, Fan Tang
TL;DR: TAG-MoE introduces Predictive Alignment Regularization to explicitly align internal routing decisions with high-level task semantics, transforming the MoE gate into a task-aware dispatch center for unified image synthesis.
IEEE Conference on Computer Vision and Pattern Recognition (CVPR'26)
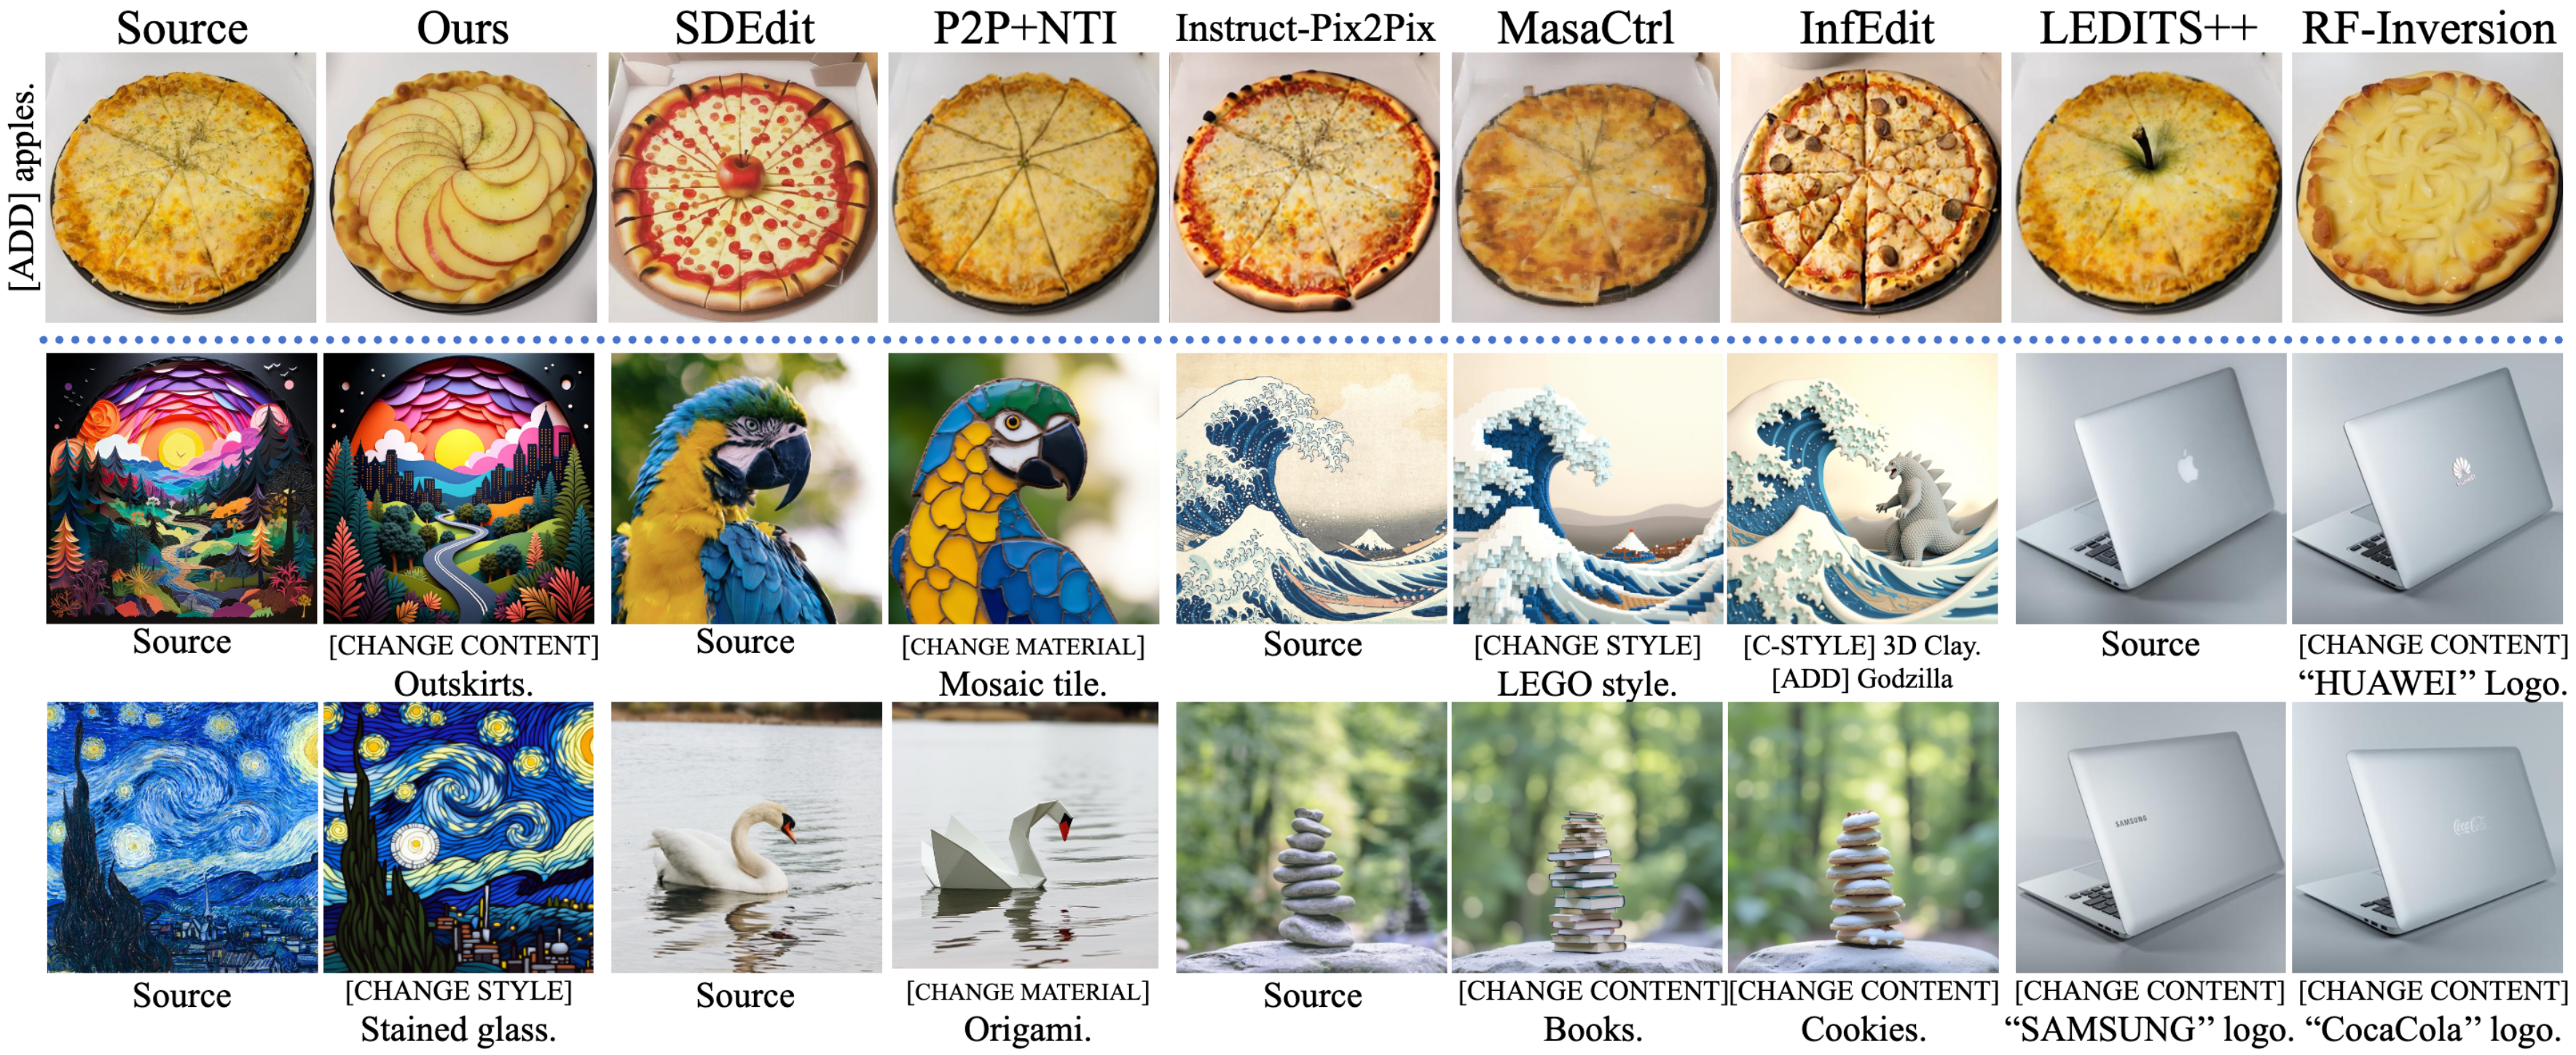
Yu Xu, Fan Tang, Juan Cao, Xiaoyu Kong, Yuxin Zhang, Jintao Li, Oliver Deussen, Tong-Yee Lee
TL;DR: HeadRouter investigates the semantic sensitivity of attention heads in MM-DiTs and introduces a training-free framework that adaptively routes and reinforces these heads for instance-specific image editing.
ACM Transactions on Graphics (TOG'26)
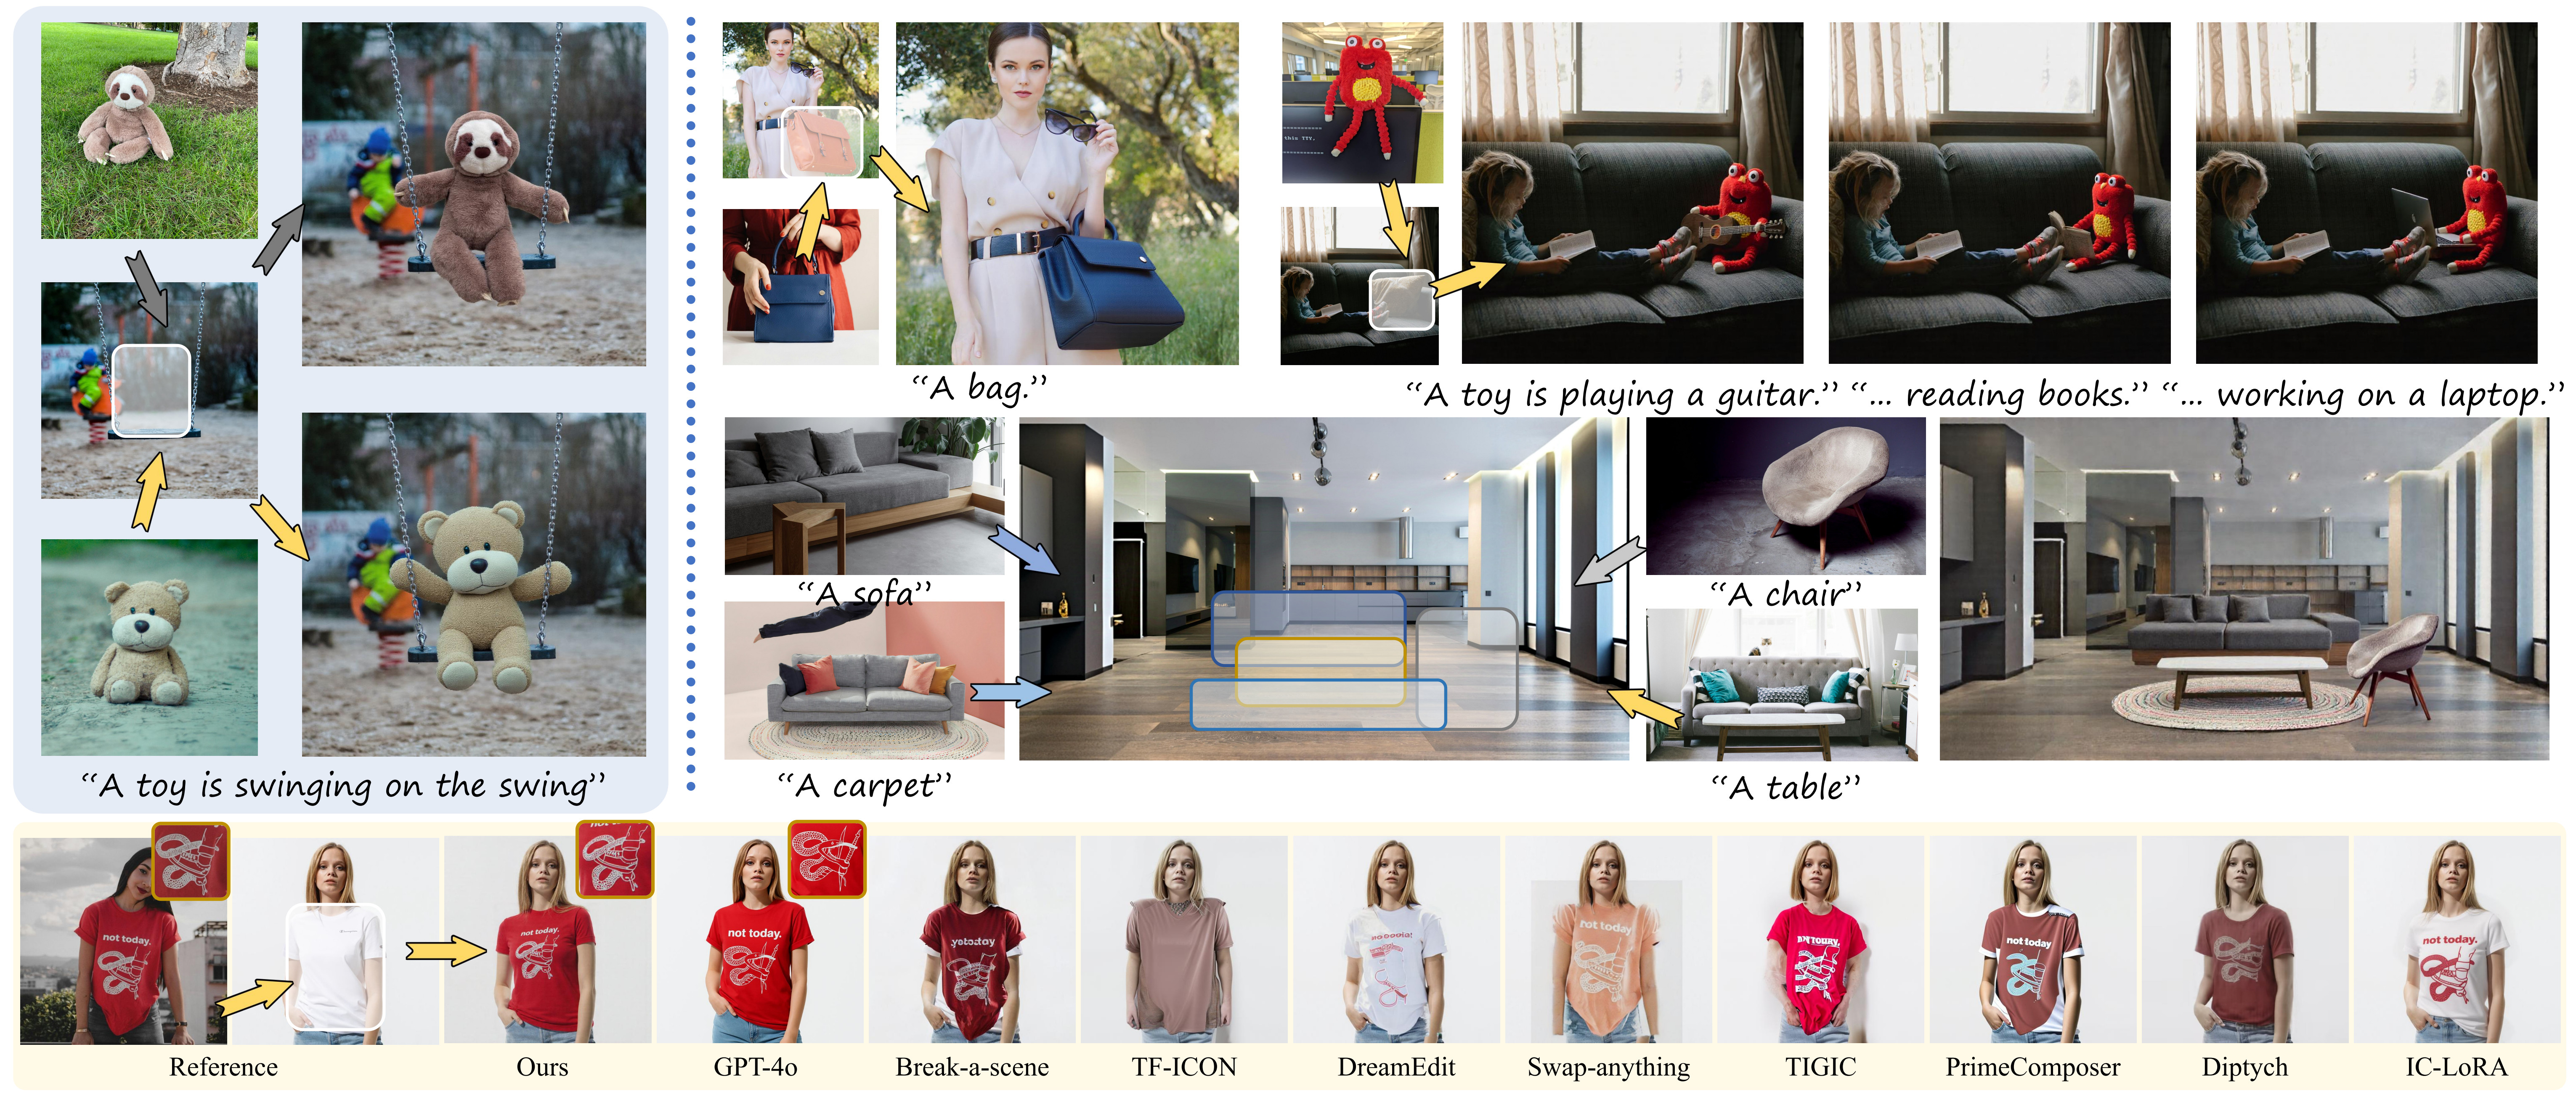
Yu Xu, Fan Tang, You Wu, Lin Gao, Oliver Deussen, Hongbin Yan, Jintao Li, Juan Cao, Tong-Yee Lee
TL;DR: In-Context Brush reformulates the task as In-Context Learning (ICL) in MM-DiTs, utilizing latent feature shifting to achieve high-fidelity, text-controllable subject injection without any model tuning.
ACM Special Interest Group on Computer Graphics and Interactive Techniques (SIGGRAPH ASIA'25)
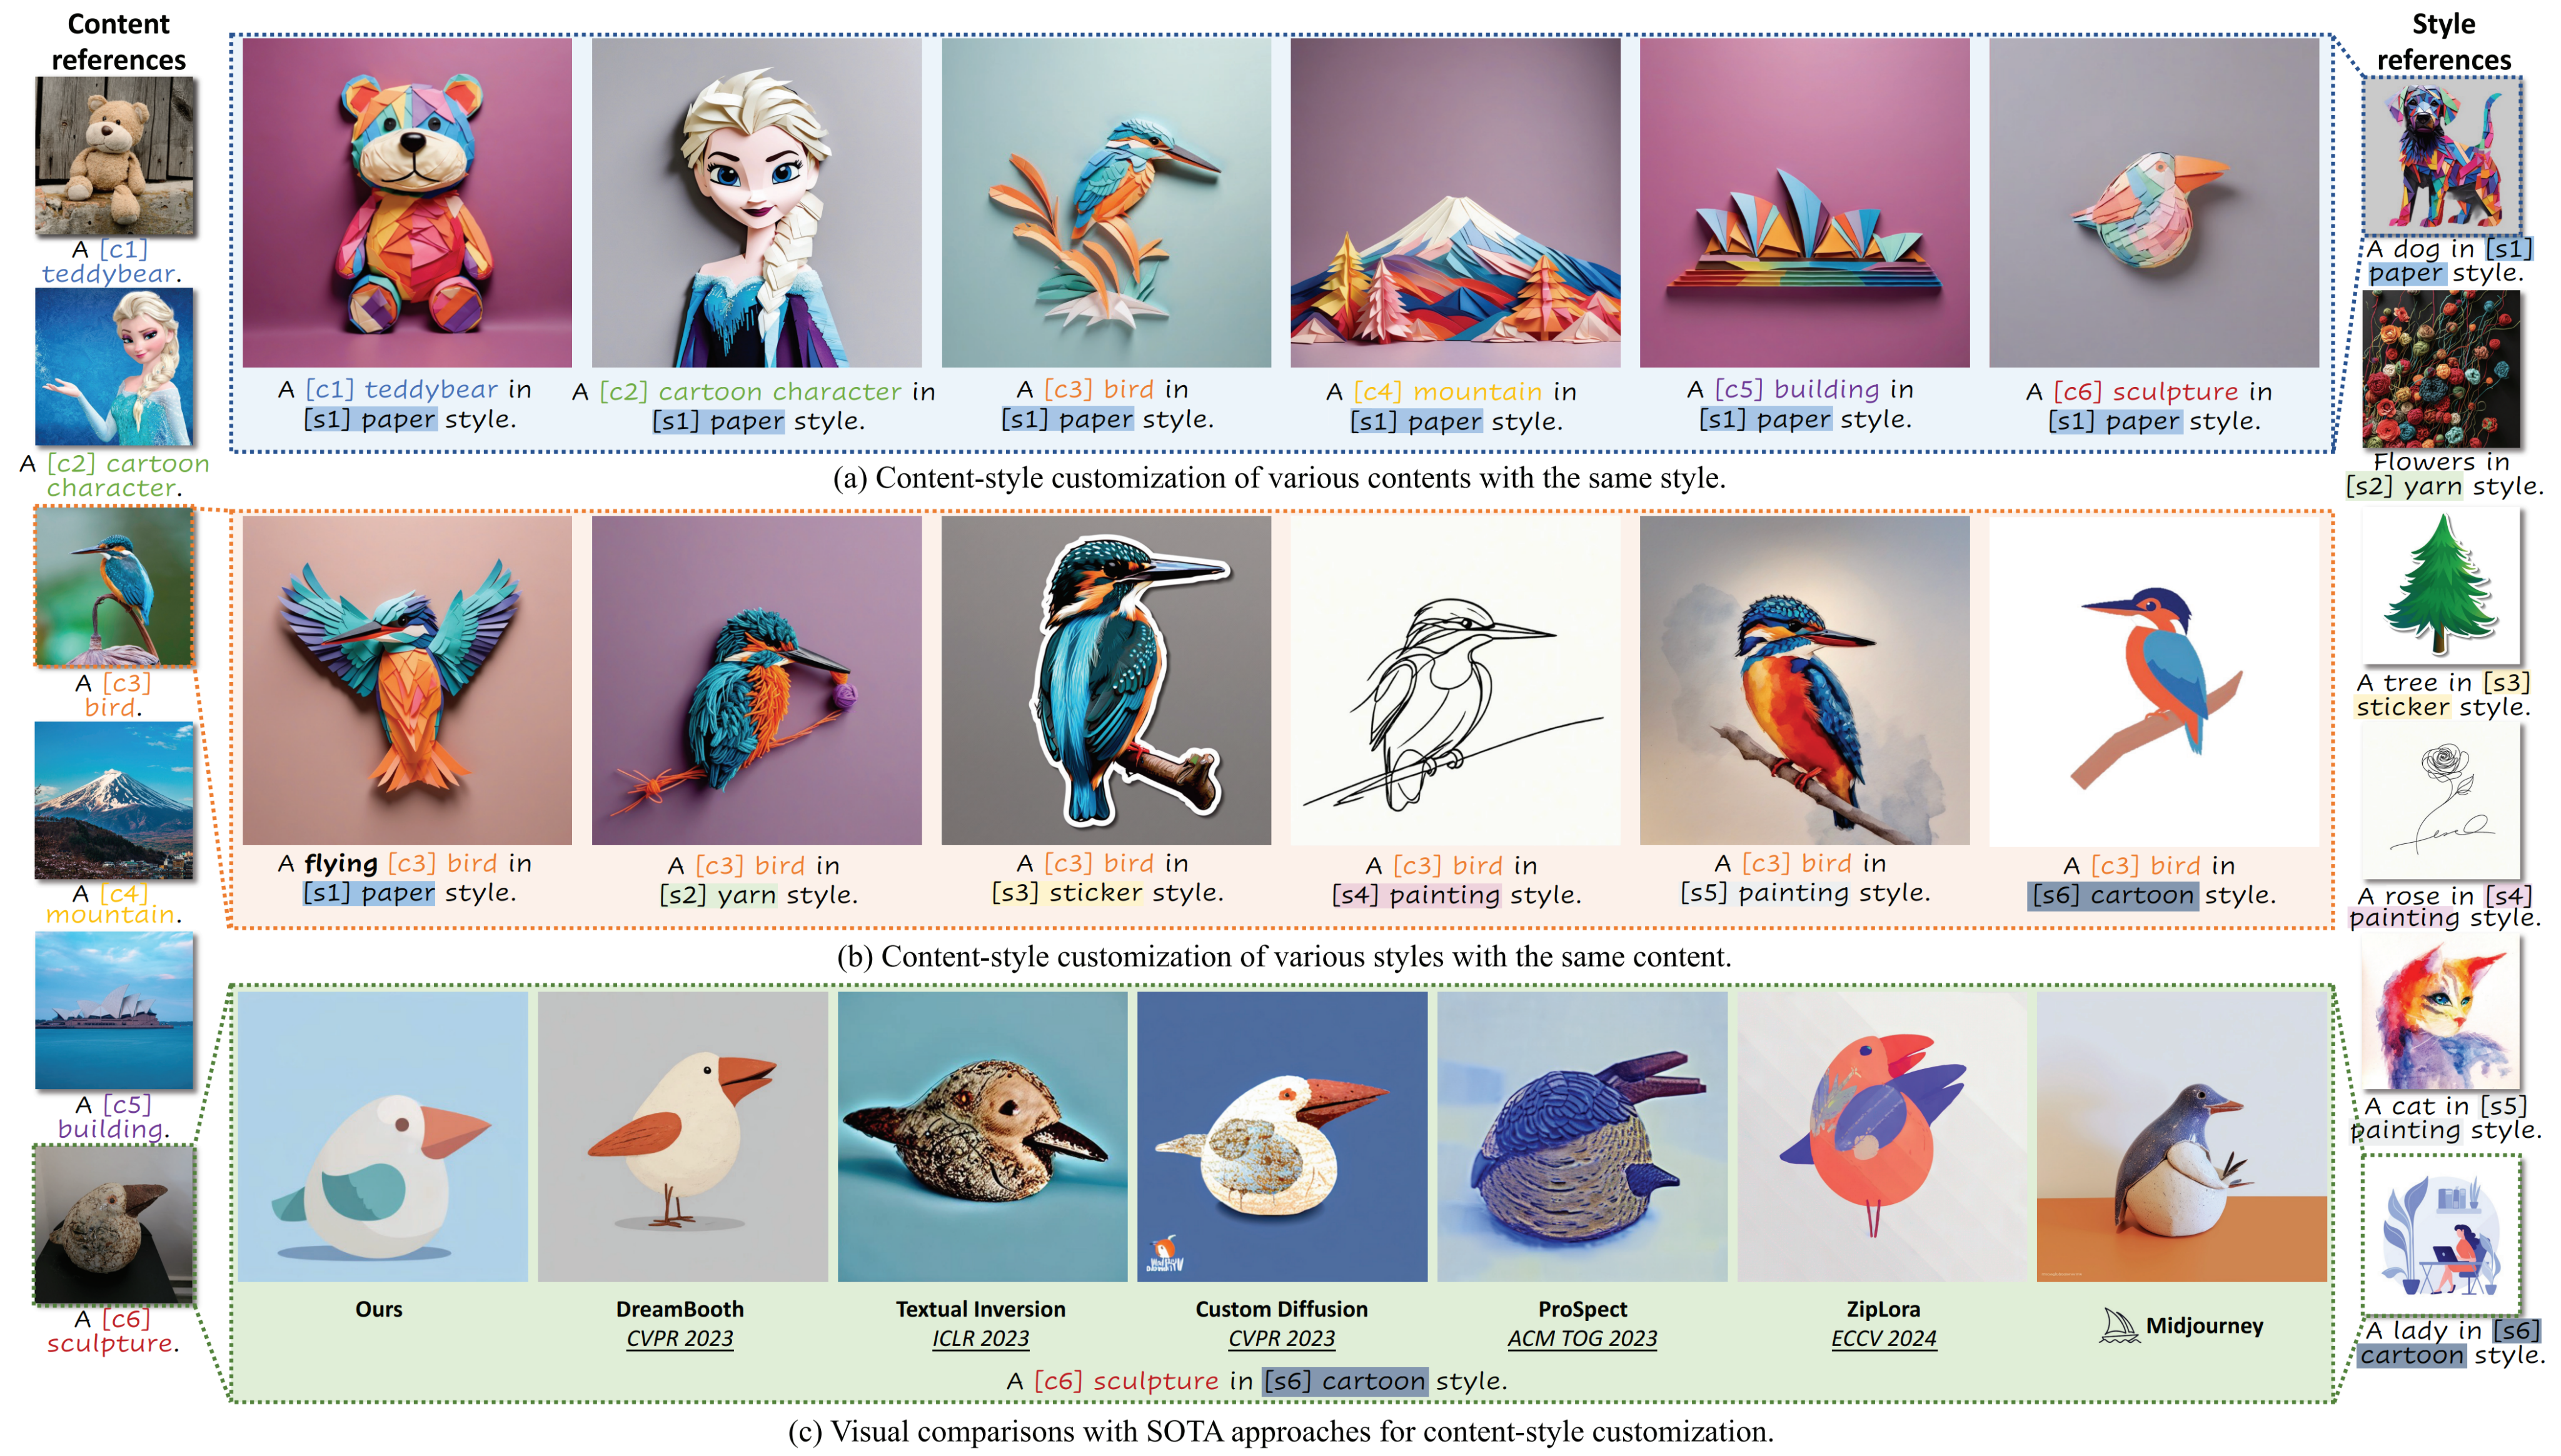
B4M: Breaking Low-Rank Adapter for Making Content-Style Customization
Yu Xu, Fan Tang, Juan Cao, Yuxin Zhang, Oliver Deussen, Weiming Dong, Jintao Li, Tong-Yee Lee
TL;DR: B4M disentangles content and style customization by separating LoRA into distinct sub-parameter spaces via Partly Learnable Projection, and harmoniously fuses them using Riemannian Preconditioning.
ACM Transactions on Graphics (TOG'25)
💻 Experience
-
2026.06 - (present), Kling AI, Full-time Researcher. Beijing, China.
Kling-Image Foundation Model.
- Responsible for the pre-training of the Kling-Image foundation model. (Work in progress)
-
2026.02 - 2026.06, Bytedance, Research Intern. Beijing, China.
Unified Multimodal Video Generation.
- Proposed SplitMoE, a split-role sparse architecture for scaling video diffusion models. (Accepted by NeurIPS 2026 as Spotlight)
-
2025.06 - 2026.02, Tencent Hunyuan, Research Intern. Beijing, China.
Unified Multimodal Image Generation based on Mixture of Experts (MoE).
-
Proposed a task-aware gating mechanism in MoE for unified image generation and editing. (Accepted by CVPR 2026)
-
Curated large-scale datasets and trained the image editing model, contributing to the visual generation capabilities of Tencent Yuanbao.
-
📑 Professional Activities
Conference Reviewer
-
2026: NeurIPS, Siggraph Asia
-
2025: ICCV, AAAI, CVPR
-
2024: ECCV, ACM MM, NeurIPS, AAAI
Journal Reviewer
- IEEE Transactions on Multimedia
💬 Invited Talks
- 2026.05, The 8th Academic Forum on Artificial Intelligence of Beijing Universities.
- 2025.05, The 7th Academic Forum on Artificial Intelligence of Beijing Universities.